A dental insurance breakdown has questions the source may not answer. The software needs to know when to leave the box alone. In our September test, GPT-6 Luna filled about half the boxes that were blank in our answer key. Altadena 1.5 left 96.9% of those boxes blank. That measures agreement with the key, not proof that every one of those boxes was unanswerable.
This is the record of that September 2026 development experiment. Altadena 1.5 was in training at the time, separate from our production service. Here’s what we tested, how we scored it, and what the results can tell us.
The sheet and the pile.
If you run a dental office, you know the breakdown sheet. Before a visit, somebody works out what the patient’s plan covers: coverage percentages, how often, age limits, deductibles and maximums. At a dental group we work with, that sheet has about 290 boxes.
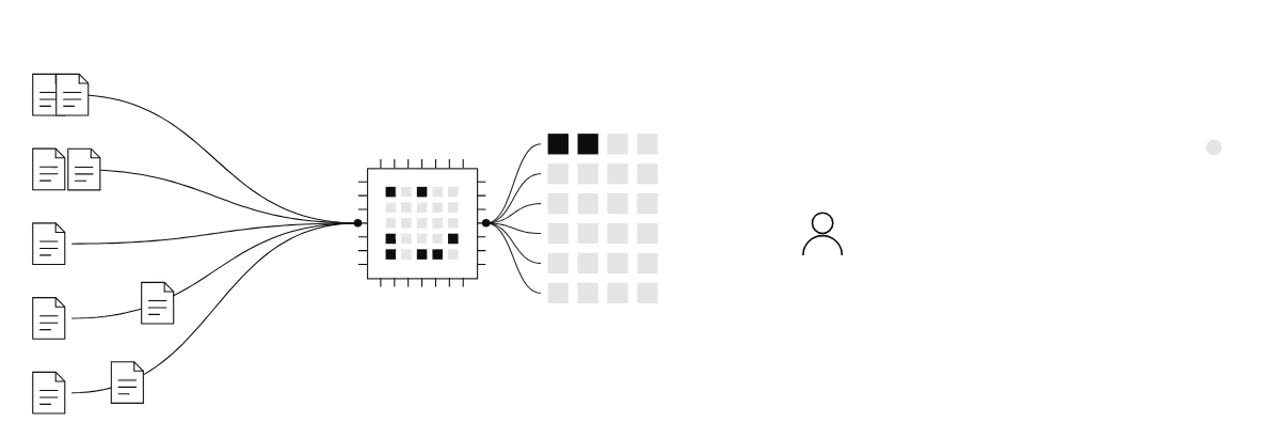
At the time of this test, our overnight check filled it in with rules written by hand for each insurer. It logged into the portal and saved the information, then turned that pile into the sheet. We were testing whether a model could take over the reading.
Reading is the hard part. For one patient, the portal hands back machine answers, web pages and plan PDFs, and a typical file is a novel’s worth of text. Only about 1 line in 20 holds an answer. And about half the answers aren’t written down directly. The portal says “covered age 14 and over,” and the box wants “>=14.”
The answer key.
How do you teach a model this, and grade it? You need an answer key. We built 127 breakdown sheets, and AI auditors checked filled boxes against the portal data and the plan’s published documents. A box without a supported answer stayed blank, although the resulting key still contained inconsistencies that needed review. That’s 36,813 boxes in all. The model trained on 117 sheets, and we held back the other 10 for the test.
The key also sets a floor. Guess the usual answer for each box without reading anything, and you’ll get 59% right. Guess from the same insurer’s other patients, and you’ll get 68%. A model only counts as smart if it clearly beats that.
Three tries.
We tried Jev first, TypeSafe’s fast model that picks answers from a list. It reads about 32,000 word-pieces, or tokens, at a time, and it got lost in long, messy files. It scored about 60% untuned and 77% tuned. Those figures come from smaller test groups, not the 10 sheets below.
Next came OpenAI’s GPT-6 Luna, a big model that thinks before it answers and reads the whole file in one go. We gave it a one-page rulebook of what each box means, and it did well on boxes with an answer. But it also filled in about half the boxes that were blank in the answer key. Our Luna setup didn’t produce the per-answer scores used by our model.
Then we built our own. It’s a 4-billion-parameter language model, small enough to run on one graphics card. We gave it a small add-on that learns from the answer key, and 290 answer buttons, one per box. Each button can only pick from the sheet’s own list of answers, like “80%,” “2x/ 1yr,” “<=18” or blank. It can’t make one up. Every button also produces a model score that we can use to set an answering threshold. It reads the whole file once and presses all 290 buttons in one go.
Training ran overnight on one rented graphics card: five rounds of about two hours each, about $26 in total. One round fixed a quiet problem. Some files are huge, and cutting them short during practice had been teaching the model to guess.
How we scored the test.
Both models were scored on the same ten cases, held out of Altadena’s training. The insurers were represented in the training set. For the filled-field comparison, we scored 1,369 fields with reference answers in the supported field types and answer vocabulary. An exact match counted as right. A missing prediction on one of those fields lost credit. Fields with blank reference answers were excluded from this comparison, not counted as wrong for being blank.
“Filled” is the share of those 1,369 fields the model answered. “Wrong among filled” is the share of its answers that disagreed with the key. Those are different denominators. The first two rows below use the broader sheet comparison, including reference blanks. Agreement with a blank reference does not establish that the source had no answer; those blanks need auditing too.
This was a small internal development test. The answer key was built with AI auditors and has known inconsistencies. Fields on one sheet share the same plan and source documents, so 1,369 fields are not 1,369 independent cases. The results describe these ten sheets, not a proven advantage across all insurers, an independent audit, or the accuracy of the finished service. The timing and cost figures cover model inference, not gathering information, human review, or delivery to a practice.
| Altadena 1.5 | GPT-6 Luna | |
|---|---|---|
| Agreement with the key, including blanks | 93.0% | 70.9% |
| Reference blanks left blank | 96.9% | 48.3% |
| Reference-filled fields right | 90.4% | 86.6% |
| Reference-filled fields answered | 97.4% | 92.1% |
| Wrong among what it filled | 7.3% | 5.9% |
| Per-answer scores in this setup | Yes | No |
| Inference time per sheet | ~6 s | ~72 s |
| Inference cost per 1,000 sheets | ~$9 | ~$13 |
On the broader sheet comparison, Altadena agreed with the key 93.0% of the time and GPT-6 Luna 70.9%. Much of that gap comes from leaving reference blanks blank. On the 1,369 reference-filled fields, the gap was smaller: 90.4% against 86.6%.
Altadena answered more of those fields: 97.4% against 92.1%. But among the answers given, it also got more wrong: 7.3% against 5.9%. More completed boxes and fewer errors are two different things. Both matter.
We also tried an answering threshold on a separate development run, r5; the comparison above used r3. At a model-score cutoff of 0.95, r5 answered 76.5% of the reference-filled fields and got 0.9% of those answers wrong. We inspected those cutoffs on the same ten test sheets. That is a development observation, not an independently validated error rate or a promise that a score of 0.95 means a 95% chance of being right. Choosing a threshold and measuring its performance require separate data.
What’s still hard.
Four things are still hard. We’ve only tested it on insurers it practiced on, and new portals come next. Copay plans are hard for every model we tried, and each scored about 70% on them.
Some files are longer than it could practice on, because the chip ran out of memory. And the answer key disagrees with itself in a few places, like “12 months” in one place and “1 year” in another. These inconsistencies can change the grade without changing whether an answer is useful. They need fixing before a stronger performance claim.
What this test told us to do next.
Our plan after this test was to map the sheet with the group: every box, every allowed answer and every rule, written down once. We also needed complete portal captures and plan documents, so the model could read all the available evidence.
The next target was more than 1,000 checked sheets: one model drafts with source references, another answers independently, and disagreements go through review. We also needed room for whole files during training and a test on insurers the model had never seen.
Before relying on an answering threshold in production, we needed fresh calibration data and a separate test, plus a review path for unresolved fields. A box marked verify beats a box filled in wrong. For the wider service and the work at the front desk, read Guest experience: your dental team has better things to do.
If your front desk still builds breakdowns by hand, write to us. We’ll go through a blank copy of your sheet with you, box by box.